As a freelancer, I sell my days, and unfortunately I only have so many :) So here is the dream I have: you could work with me without me being in the room. You'd ask your own AI a marketing question, and it would look at it the way I would. You could call it productizing myself (haha). That's what I'm trying to do, actually!
Since April I've been trying to make open-weight models, and my own workflows, look a bit more like me. It's early and, honestly, most of what I tried hasn't worked yet, but I'd rather show it now than wait for a nice result.
If you've never done it, here's what fine-tuning means, and it's simpler than it sounds. A model like the one behind ChatGPT learned from a huge pile of text written by everybody. That's why it answers like a reasonable average person. Fine-tuning means taking that model and training it a bit more, on your own examples this time. It's still the same model, but on the kind of question you showed it, it starts to lean your way.
On the left, 2 boxes: a general model, trained on everybody, and my examples, how I would answer. Both go through training and give, on the right, the same model, a bit more like me on that kind of question.
What open weights means
A model like Claude or GPT lives on someone else's servers. You can give it instructions, but you can't change the model itself.
An open-weight model is different: the weights are the billions of numbers that make the model what it is, and the company that trained it publishes them. So you can download the file and run it on your own computer. But it goes further than that: you can change it. You can train it a bit more on your own examples, plug a small trained piece into it, or shrink it so it fits on a laptop.
Training isn't the same as pasting examples into a chat. Pasted examples are gone when the chat ends. Training changes the model, so it keeps what it learned.
That last part is the one I care about most, because you can't make a model yours if you can't touch it. Qwen, Gemma and Mistral are open-weight models, and Claude and GPT aren't.
2 rows. Closed: your prompt goes to their servers, and you rent the answers. Open weights: your prompt goes to the model file, on your own machine, and you can run it, train it and shrink it.
Why I think it's worth trying
2 things make me think so, and the first one is that we now have a lot of data about ourselves. My memory tool holds a bit more than 7,000 of my conversations with AI. My dictation app has kept 473 voice clips, a bit over 4 hours of me talking, and my calls are transcribed. An agent can read all of that and write down the patterns: the questions I ask first, what I look at, what I refuse. Before, that only lived in my head. Now it's material that should be useful again and again. And with AI, it seems I can finally do something with it!!
The second one is that, in my field, the answer is rarely yes or no. Marketing, sales, design, art: there is no test that passes or fails, and you'll see below how hard that made my own testing. What a client buys in those fields is judgment. A general model was trained on everybody, so it gives the reasonable, average answer. I want to find out if a model can carry one person's judgment, with their taste and their biases.
If it can, a freelancer could exist in a second form: something your own Claude or Codex calls when it needs a second opinion.
Attempt 1: teach a small model how I diagnose
In April I wrote up 12 go-to-market diagnoses. Each one takes a company's situation and says what I think is wrong and what to do first. Some are companies I only know from the outside, and others come from my own work.
Building those 12 examples took me far more time than the training itself. For each case I had to write the situation down, read what the model answered, and leave my feedback, case after case, version after version. I'm happy I could do it by voice!
Then I trained a LoRA on them. A model is a stack of layers, and a LoRA is a set of small pieces added next to some of those layers, the last 16 in my case. The model's own numbers don't move at all, and only the small pieces learn. Here's how training goes: the model reads a situation and writes its diagnosis. That gets compared with mine, and the small pieces are adjusted so the next try lands a bit closer. One round like that is called a training step, and each run did 100 of them, so the model went through each of my 12 examples about 8 times. I used MLX, Apple's library for running and training models on a Mac.
A model drawn as a stack of layers. The first layers are plain: the model's own layers, billions of numbers, not changed. Next to the last layers sit small shaded pieces: pieces added next to the last 16 layers, the only part that learns. On the right, a box, 12 diagnoses, my examples, with an arrow marked train that points at the shaded pieces only.
In the names below, the number is the size of the model: 7B means 7 billion numbers. Bigger usually means smarter, slower and hungrier for memory.
| When | What I ran | What happened |
|---|---|---|
| 1 April | Qwen2.5 7B | The first run: on 3 test cases it beat the same model without my training on 2, and lost on 1. Enough to keep going |
| 1 to 10 April | 10 versions on the 7B | 1 got stuck repeating itself and 1 was trained on old files, so it counted for nothing: 4 or 5 hours lost |
| 19 April | Qwen2.5 14B and 32B, Gemma 3 27B | Same thing, but on 3 bigger models. None clearly better than the others |
| 21 April | Qwen3 30B | It never started, because Apple's library crashed with this newer model on the 2 versions I tried, so I couldn't train it at all |
So why didn't I release the first one, if it won 2 times out of 3? Because it only beat the same small model without my training, on 3 cases, and a 7B model is far from Claude with or without me in it. Winning that match didn't make it useful.
Each run was small: 100 training steps and about 150,000 tokens, roughly 20 to 30 minutes of my computer screaming like hell, and my girlfriend complaining!
That's why I ended up spending too much money on a way too powerful MacBook, an M5 Max with 128 GB of RAM (it is a beast). Every day I still believe it gives me peace of mind and room to experiment, and local models are getting so much better! I think it's worth it if you have a little money to spend, in your company or not :)
The test
A small model on its own is no match for Claude. So, in practice, the useful test was to use it as a helper. The fine-tuned model writes a short memo with its diagnosis, and Claude reads that memo before giving its own answer. The question was simple: does Claude answer better with my memo than without?
2 rows. First row: the case goes to Claude, which gives an answer. Second row: the case goes to my model, which writes a memo, then to Claude, which gives an answer. Both answers are scored against my own diagnosis.
I took one real case from my own work and compared 3 setups. In the easy version of the test, the model gets all the information up front. In the harder one, it only gets a short brief. It has to ask its own questions first, and the answers come from a fixed list, so every setup gets the same information. An AI reviewer then scored each answer against a checklist built from my own diagnosis of that case.
| Setup | Score | What I saw |
|---|---|---|
| Claude alone | ★★★★★ | A solid diagnosis: it asked 12 questions and found the real problem by itself |
| Claude, helped by my fine-tuned 32B | ★★★★★ | No better: twice, my model pushed the same idea, "install tracking first", which was wrong for this case, and Claude read it and set it aside |
| Claude, helped by my fine-tuned Gemma | ★★★★★ | Same score, by a slightly better road. My model suggested a question Claude hadn't asked, and killed a bad idea early (cutting prices) |
So it's a tie: 5 stars for all 3, which is 10 out of 10 on the checklist. When everybody gets the top mark, the test can't tell them apart, so it says more about my test than about my models. And in the easier version, one of my fine-tuned models finished its answer stuck in a loop, with invented jargon.
I also compared my 3 bigger models head to head, on 3 cases, with another model as the judge: here are 2 answers, which one is better? That's 3 pairs on 3 cases, so 9 verdicts. 3 of them flipped when I swapped the order of the 2 answers. A judge that changes its mind because B came before A is partly judging the order, so I couldn't trust the judge either.
2 rows. First row: answer X, then answer Y, go to the judge, and X wins. Second row: answer Y, then answer X, go to the same judge, and Y wins. It happened on 3 of the 9 pairs.
It's not like code, where a review points at something you can check. "Which diagnosis is better" is a matter of judgment, and that's exactly the kind of question this note is about.
And here's the part I'm least proud of: I was supposed to read the outputs blind myself, without knowing which setup wrote what. The packs were built in April and I never did it, so it's still on my todo, 6 months later.
A chart over the time of training, from its start on the left to its end on the right. A solid line, the error on new examples, goes up all the way. A dashed line, the error on my 12 examples, goes down all the way.
Here's what I take from it:
- 12 examples is tiny: during training, the error on my 12 examples kept going down while the error on examples the model had never seen went up. That's a model learning the answers by heart instead of learning how to think
- One case and an AI judge can't conclude anything: it's n=1
- My best guess, on one case: Claude with good context was already doing the hard part, so my small model had little left to add
Attempt 2: wrap my method in tools
In May I tried without any training: I turned my way of diagnosing into 5 tools an agent could call one after the other. Then I compared that with plain Claude.
The review of that test was clear. Plain Claude gave most of the value in 17 seconds. My tools took 5 minutes and 7 seconds to give a more careful version of the same thing. There wasn't much to discuss, so I paused it.
2 hand-shaded bars across the full width. Plain Claude: a very short bar, 17 seconds. My 5 tools: a bar 18 times longer, 5 minutes 07.
What works today uses no training
My dictation runs on 2 local models straight off the shelf. Qwen2.5 14B cleans up what I say, and Qwen2.5 32B rewrites it as a prompt. You can see both in my setup. The only thing I gave them is instructions. I ran the same dictations through 5 models before keeping these 2. One of the 3 I dropped was faster, but it added ideas I never said.
Writing is where it fails most clearly. I gave the agents pages of instructions about my voice. This month I asked for a LinkedIn post, threw away 3 drafts and typed it myself, because no model writes like me today. I haven't trained one yet, because 4 hours of raw dictation isn't clean training material. I still intend to come back to it, with all the voice material and the transcripts I have, but it will take much more time than you'd think!
In May I also trained an image model on 23 photos of my face. That's the most literal version of this whole idea, I guess.
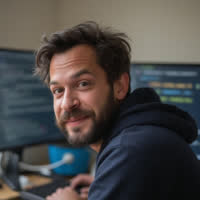
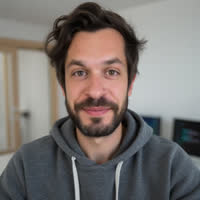
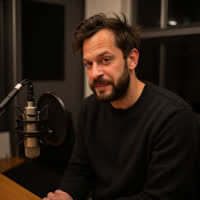
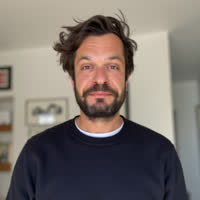
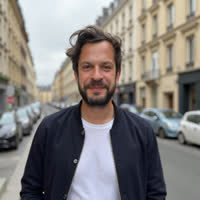
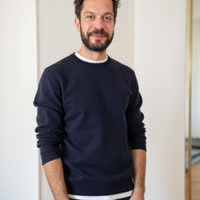
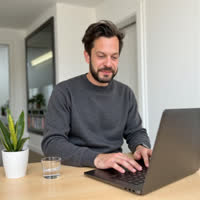
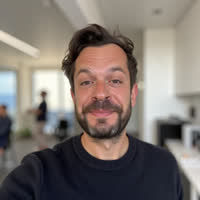
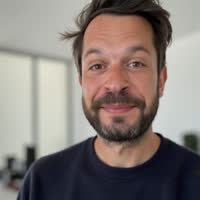
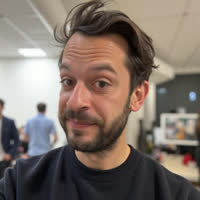
A grid of 12 small pictures of a man with dark hair and a beard: at a desk in front of screens, in a street, in an office, at a microphone, at a laptop. All were made by the image model.
A voice, too
There's one more thing in the works. Every time I dictate, the audio is kept too, not just the text. That's 473 clips, a bit over 4 hours of me talking, in French and in English.
I'm using those samples to train a copy of my voice with ElevenLabs. I don't have a plan for it yet, maybe dubbing videos or maybe YouTube, but I have the material. Here is the same sentence twice, once said by me and once by the copy:
2 short audio clips of the same sentence: Hey, how is it going for you so far? Do you enjoy the read? The first one is me, recorded with a microphone, 5 seconds. The second one was generated by ElevenLabs from a copy of my voice, 4 seconds. The files are /posts/fine-tuning/voice-me.m4a and /posts/fine-tuning/voice-elevenlabs.mp3.
What I'm building now
In October I restarted in a different order: first I test if the answers are better, and only then do I build the product around them.
The idea is a second opinion on marketing decisions that your own agent can call. You work in Claude or Codex, on your own data. When there's a decision to make, your agent asks mine, through a connector: what's missing, which question nobody asked, and whether I'd go or not. It doesn't decide for you, the same way no agent decides for me. It gives you the opinion I'd give, and then you decide. On your side, it would be just one connector to add. It isn't built yet, so the details can still change. I'd like people to feel like they're working with me, through the tools they already use every day.
3 boxes in a row. You talk to your agent, which is Claude or Codex, working on your own data. Your agent asks my second opinion, which answers with what's missing and whether to go or not.
Fine-tuning is paused for now, and the first version is Claude with my method written as a prompt, my cases to compare with, and a review step. Before building anything around it, I want to know if it's visibly better than Claude on its own.
So I set up 3 versions: plain Claude, Claude with a strong prompt that reviews its own answer, and Claude with my prompt and my review step. I ran all 3 on 8 cases, 24 runs in all. The answers are labelled A, B and C, and a key I haven't opened says which is which, and that's what blind means here.
I read them this week, and my first impressions are these: on 2 of the 8 cases, all the answers felt the same to me. On the other 6 I had a favourite, but I don't know yet which version it was. The version with my review step also took 2 to 5 minutes per answer, which is way too slow when someone is waiting in a chat.
A grid of 8 cases against 3 answers, A, B and C. Case 1: all felt the same. Case 2: leaning B. Case 3: A or B. Case 4: B. Case 5: all felt the same. Case 6: C. Case 1 with a change: C. Case 2 with a change: A. Under the grid, a dashed box: the key, which letter is which version, not opened yet.
If I can't tell my version from plain Claude without the key, there's nothing to sell. It's as simple as that, and I'd rather know that now.
What I don't know
- If 30 good examples would change the fine-tuning result, or if it takes 300
- If a model can write like me at all. I haven't tested that with training
- If anyone would pay for a marketer's review delivered through their agent. I found no public example
- If a small trained model only helps when the big one is weaker, or has less context
- How to use the insane amount of data I have on my Mac, all my exchanges with AI, to pull my judgment out of it and encode it. I'm still wondering
Why I keep going
I'm curious, and I like to try things before I know what they're for.
What I noticed along the way is that my tools feed each other. I set up dictation to type less, and it left me 4 hours of my own voice. I built a memory so my agents stop forgetting, and it left me 7,000 conversations to learn from. I wrote diagnoses for clients, and they became training examples. None of that was the goal, but each tool leaves material that the next one can use, and somehow that adds up.
3 rows of 3 boxes. Dictation left 4 hours of my voice, which could feed a voice of my own. Memory for agents left 7,000 conversations, which could feed how I reason. Client work left 12 diagnoses, which could feed a second opinion.
I think this is part of the future of freelancers, especially in fields where the answer isn't yes or no. Today it mostly doesn't work for me, and I may be wrong about the whole thing. But the 2 reasons at the top haven't changed. What failed is my first way of doing it, with 12 examples.